Setting the Stage: TechCrunch Disrupt 2026’s “Open vs Closed AI” Session
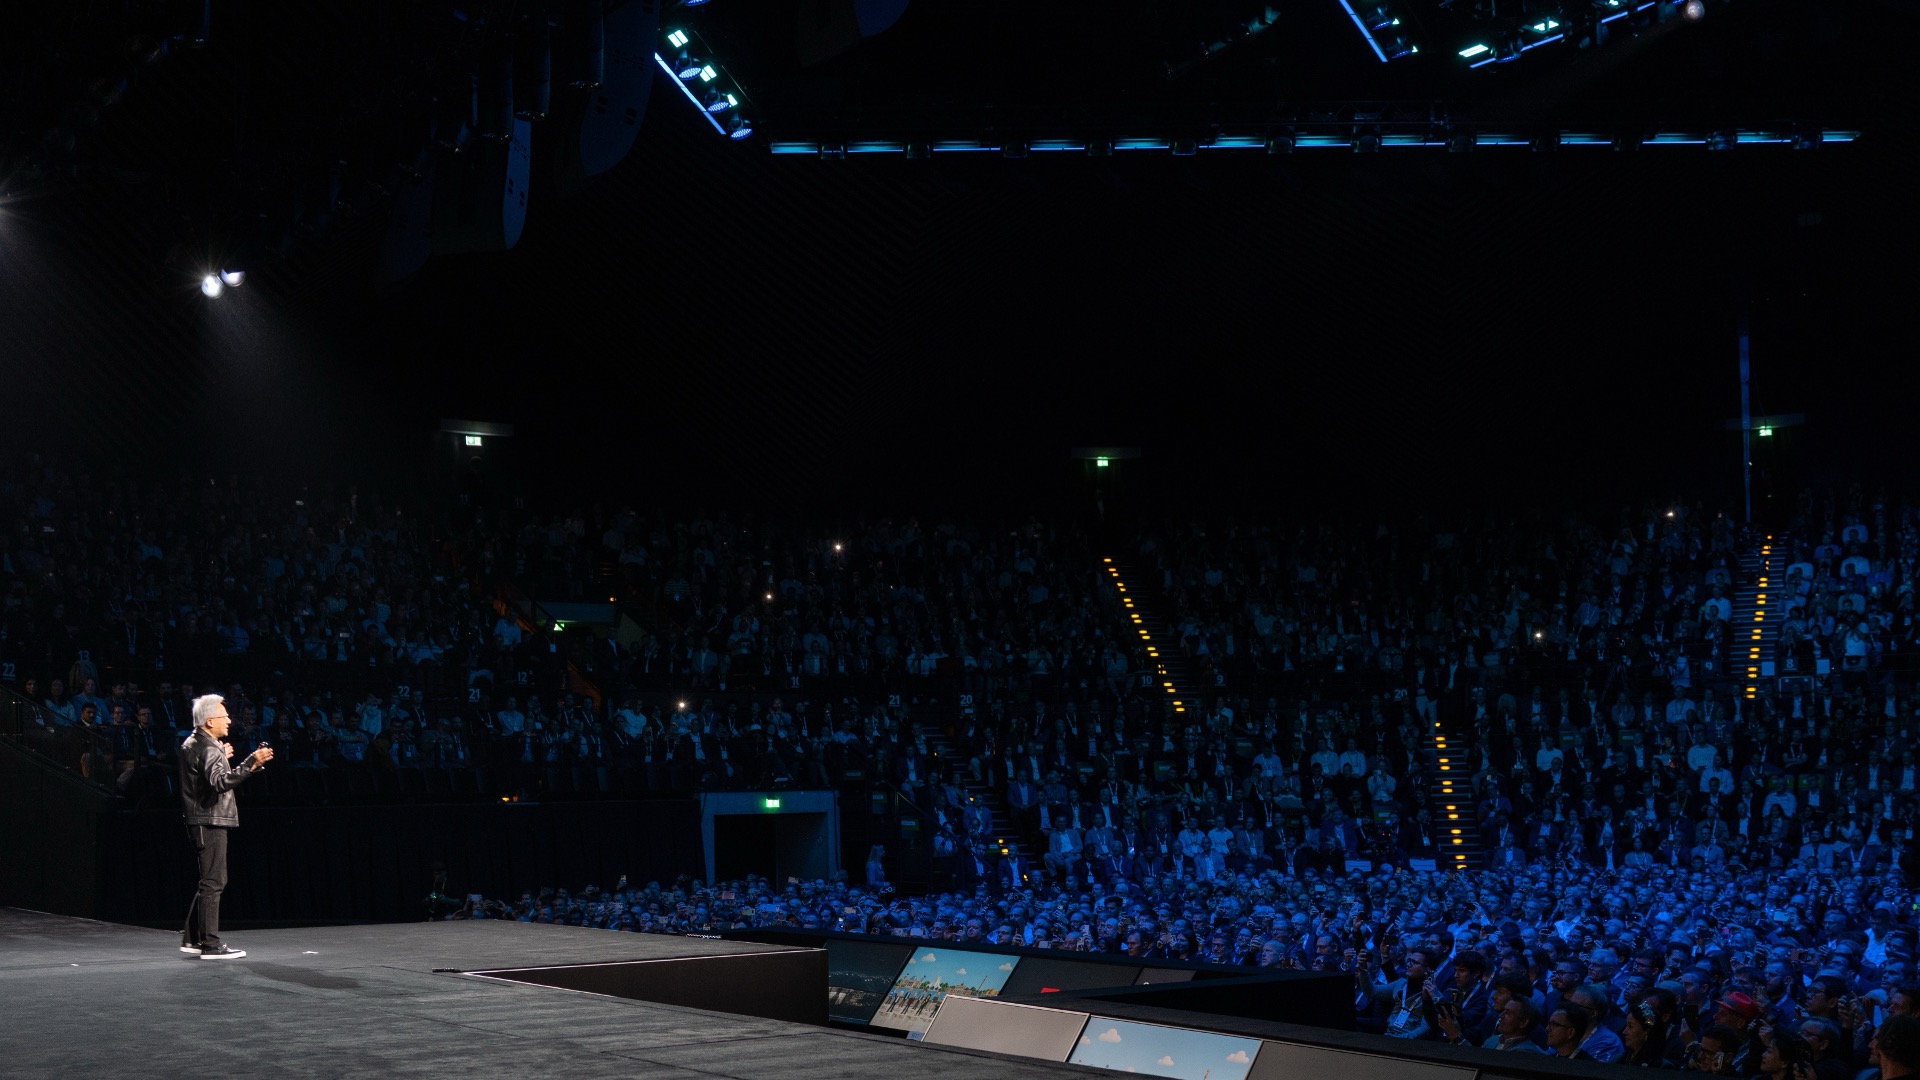
The Builders Stage in San Francisco buzzed with more than 10,000 tech leaders from October 13‑15, 2026. Among the packed agenda, the panel titled “The Open vs. Closed AI Debate Is Just Getting Started.” drew particular attention because it framed a decision that now feels as strategic as choosing a cloud provider.
Nvidia’s own Nader Khalil, Director of Developer Tech and co‑founder of the recently acquired Brev.dev, shared the stage with Sydney Sykes, Global Head of VC Partnerships, while Jensen Huang punctuated the discussion with a memorable line: “the future is not proprietary versus open, but proprietary and open.”
The conversation was not a philosophical debate about licensing; it was a hard‑nosed business analysis of how model choice influences startup costs, infrastructure flexibility, margins, differentiation, speed to market, and long‑term control. The session’s relevance is amplified by the simultaneous launch of Nemotron 3 Super, Nvidia’s 120‑billion‑parameter open model, and the growing adoption of Brev.dev’s multi‑cloud deployment tools.
Why the Open vs Closed AI Decision Matters for Startups
Cost Structure
- Open‑source models eliminate per‑token licensing fees, but they still demand compute, storage, and engineering resources.
- Proprietary frontier models (e.g., OpenAI’s GPT‑4‑Turbo, Anthropic’s Claude) often bundle compute costs into a usage‑based price, which can be attractive for early‑stage teams that lack deep‑learning expertise.
A typical early‑stage AI startup may spend $0–$5 k/month on GPU time when fine‑tuning an open model on a modest dataset. By contrast, a comparable workload on a proprietary API can range from $5 k–$15 k/month, depending on request volume and latency requirements. The difference becomes a decisive factor when runway is measured in months rather than years.
Infrastructure Flexibility
Brev.dev’s platform, now part of Nvidia, offers a single‑pane‑of‑glass interface to spin up workloads on public clouds, private clouds, or on‑premises clusters. This flexibility directly addresses the “single‑compute source lock‑in” risk that many founders cite when evaluating closed APIs.
“If you’re locked into a single provider’s endpoint, you lose bargaining power and may face sudden price hikes or service deprecations,” Khalil noted.
Margins and Differentiation
Open models empower startups to own the entire stack—from data ingestion to model serving—allowing them to embed proprietary data pipelines that create a defensible moat. Proprietary models, while fast to integrate, limit differentiation because every competitor can query the same endpoint with similar prompts.
Speed to Market
Closed APIs shine when time‑to‑value is paramount. A SaaS product that needs a conversational assistant can integrate an API in days, whereas building a custom fine‑tuned open model may take weeks of data engineering and GPU provisioning. The decision often hinges on the startup’s go‑to‑market timeline.
Technical Breakdown: Nemotron 3 Super and Brev.dev
Nemotron 3 Super – An Open Model Built for Agents
- Parameter count: 120 billion
- Release date: March 2026
- Target workloads: Agentic reasoning, multi‑step planning, and tool‑use scenarios (e.g., robotics, autonomous vehicles, biomedical simulations)
Nemotron 3 Super’s architecture emphasizes efficient attention mechanisms that reduce memory overhead by up to 30 % compared with earlier 175‑billion‑parameter models. The model’s training data includes a curated mix of robotics logs, autonomous‑driving telemetry, and peer‑reviewed biomedical papers—evidence of its breadth is the 145 papers accepted at ICML 2026 that cite the model.
For startups, the open nature of Nemotron 3 Super means:
- No per‑token fees – only compute costs.
- Full weight access – you can prune, quantize, or distill the model to fit edge devices.
- Community tooling – a growing ecosystem of adapters, LoRA scripts, and evaluation suites.
Brev.dev – Decoupling Compute from Vendor
Brev.dev’s core proposition is infrastructure agnosticism:
- Public cloud support: AWS, GCP, Azure – with auto‑scaling GPU pools.
- Private cloud & on‑prem: Integration with Kubernetes, OpenShift, and bare‑metal GPU racks.
- Unified API: Developers write once, deploy anywhere, avoiding lock‑in to a single compute vendor.
The platform also provides cost‑optimization dashboards that surface real‑time GPU utilization, enabling startups to right‑size their clusters and keep OPEX low. In practice, a seed‑stage startup can prototype on a single V100 instance, then expand to a multi‑node DGX‑H100 farm without rewriting deployment scripts.
Strategic Implications for Startup Founders
Decision Matrix
| Factor | Open‑Source (e.g., Nemotron 3 Super) | Proprietary (e.g., OpenAI, Anthropic) |
|---|---|---|
| Up‑front CapEx | Higher (GPU procurement, engineering) | Low (no hardware purchase) |
| OPEX (usage) | Compute‑only, predictable | Variable, usage‑based fees |
| Speed to MVP | Weeks (model fine‑tuning) | Days (API integration) |
| Differentiation | High (custom data, model tweaks) | Low (shared endpoint) |
| Control & Compliance | Full (data never leaves premises) | Limited (vendor data policies) |
| Scalability | Dependent on own infra or Brev.dev | Vendor‑managed scaling |
Founders should align the matrix with their business model. A B2B SaaS that processes regulated health data may prioritize control and compliance, leaning toward open models hosted on‑prem via Brev.dev. Conversely, a consumer‑facing chatbot aiming for rapid adoption may accept the trade‑off of a proprietary API.
Funding Considerations
Sydney Sykes highlighted that VCs are increasingly scrutinizing AI spend. Funds are asking portfolio companies to demonstrate a clear path from “free tier API usage” to “self‑hosted, cost‑effective production.” Startups that can articulate a migration plan—from a closed API prototype to an open‑model production stack—are viewed as lower risk.
Security Angle
Open models are not immune to security threats. Recent research on AI‑prompt injection—illustrated by the Zoom Annotation Flaw where malicious prompts manipulated UI elements—shows that even well‑trained models can be coerced into unintended behavior. Startups must implement prompt sanitization, model‑level access controls, and continuous monitoring. For a deeper dive into AI‑driven exploits, see the analysis of the Zoom annotation issue: https://ltdeveloperblogs.github.io/posts/zoomsday-hack-uncovered-using-fewer-than-20-ai-prompts
Similarly, the Zoom Zero‑Day Exploit demonstrated how compromised AI pipelines can become a vector for remote code execution on iOS and macOS devices: https://ltdeveloperblogs.github.io/posts/zoom-flaw-let-an-attacker-take-over-your-device-including-iphone-and-mac
These incidents underscore the importance of defense‑in‑depth when deploying either open or closed models, especially in regulated sectors.
Future Outlook: Convergence, Not Competition
Jensen Huang’s assertion that the future is “
“proprietary and open,” set the tone for what many founders are already doing: building hybrid stacks that blend the rapid‑deployment advantages of closed APIs with the long‑term strategic benefits of open‑source models.
Hybrid Stacks in Practice
- Prototype on a Closed API – Use an endpoint such as GPT‑4‑Turbo to validate product‑market fit in weeks.
- Collect Proprietary Data – While the prototype runs, capture domain‑specific interactions, logs, and user feedback.
- Fine‑Tune an Open Model – Transition to Nemotron 3 Super (or another community model) using the curated dataset, applying LoRA or adapter techniques to retain the learned behavior.
- Migrate with Brev.dev – Deploy the fine‑tuned model across the chosen compute environment—public cloud for burst capacity, on‑prem for compliance‑heavy workloads—without rewriting the inference code.
This approach lets startups lock‑in early velocity while preserving the option to own the stack later, a pattern that resonated strongly with the audience at Disrupt.
What Nvidia’s Playbook Means for the Ecosystem
- Accelerated Tooling – Nvidia’s investment in Brev.dev signals a broader push to lower the operational friction of running large models locally. Expect tighter integrations with CUDA‑optimized libraries, NVIDIA AI Enterprise, and upcoming NVIDIA AI‑Ready Cloud offerings.
- Community‑Driven Innovation – The open‑source release of Nemotron 3 Super has already sparked a wave of community contributions—quantization scripts for Jetson devices, reinforcement‑learning‑from‑human‑feedback (RLHF) pipelines, and domain‑specific tokenizers. Startups can tap into these resources to shave weeks off development cycles.
- Strategic Partnerships – Nvidia’s VC arm, led by Sydney Sykes, is actively scouting startups that demonstrate a clear migration path from closed to open models. Funding rounds that include a “compute‑independence” milestone are becoming a de‑facto standard.
Recommendations for Founders
| Goal | Recommended Path | Key Nvidia Resources |
|---|---|---|
| Fast MVP | Start with a proprietary API (e.g., OpenAI) | Leverage Nvidia’s AI‑Accelerated SDKs for rapid prototyping on GPUs |
| Regulatory Compliance | Deploy open models on‑prem via Brev.dev | Use NVIDIA DGX Cloud for secure, isolated clusters |
| Cost Optimization at Scale | Transition to self‑hosted open models, apply quantization | Utilize Brev.dev’s cost‑dashboard and NVIDIA TensorRT for inference efficiency |
| Differentiation | Fine‑tune Nemotron 3 Super with proprietary data | Access community adapters and NVIDIA’s Model Optimizer tools |
| Future‑Proofing | Build a hybrid pipeline that can swap endpoints | Adopt the unified Brev.dev API abstraction layer |
Frequently Asked Questions
Q1: How much GPU hardware is needed to run Nemotron 3 Super in production?
Answer: A single NVIDIA H100 GPU can serve inference for low‑throughput workloads after applying INT8 quantization. For higher QPS (queries per second) scenarios, a multi‑node DGX‑H100 cluster (4–8 GPUs) is typical. Brev.dev’s auto‑scaling can provision additional nodes on demand, keeping latency under 100 ms for most agentic tasks.
Q2: Are there licensing restrictions on using Nemotron 3 Super commercially?
Answer: Nemotron 3 Super is released under the NVIDIA Open Model License (NOML), which permits commercial use, modification, and redistribution, provided you do not re‑license the model under a more restrictive license. The license also requires attribution and a clause preventing the model from being used for disallowed activities (e.g., weaponization).
Q3: What security measures should I implement when exposing an open model via an API?
Answer:
- Enforce strict input validation and prompt sanitization to mitigate injection attacks.
- Deploy a rate‑limiting gateway to prevent abuse.
- Use NVIDIA’s Triton Inference Server with built‑in authentication and TLS encryption.
- Continuously monitor logs for anomalous request patterns and employ a model‑level audit trail.
Q4: Can I mix multiple open models in a single application?
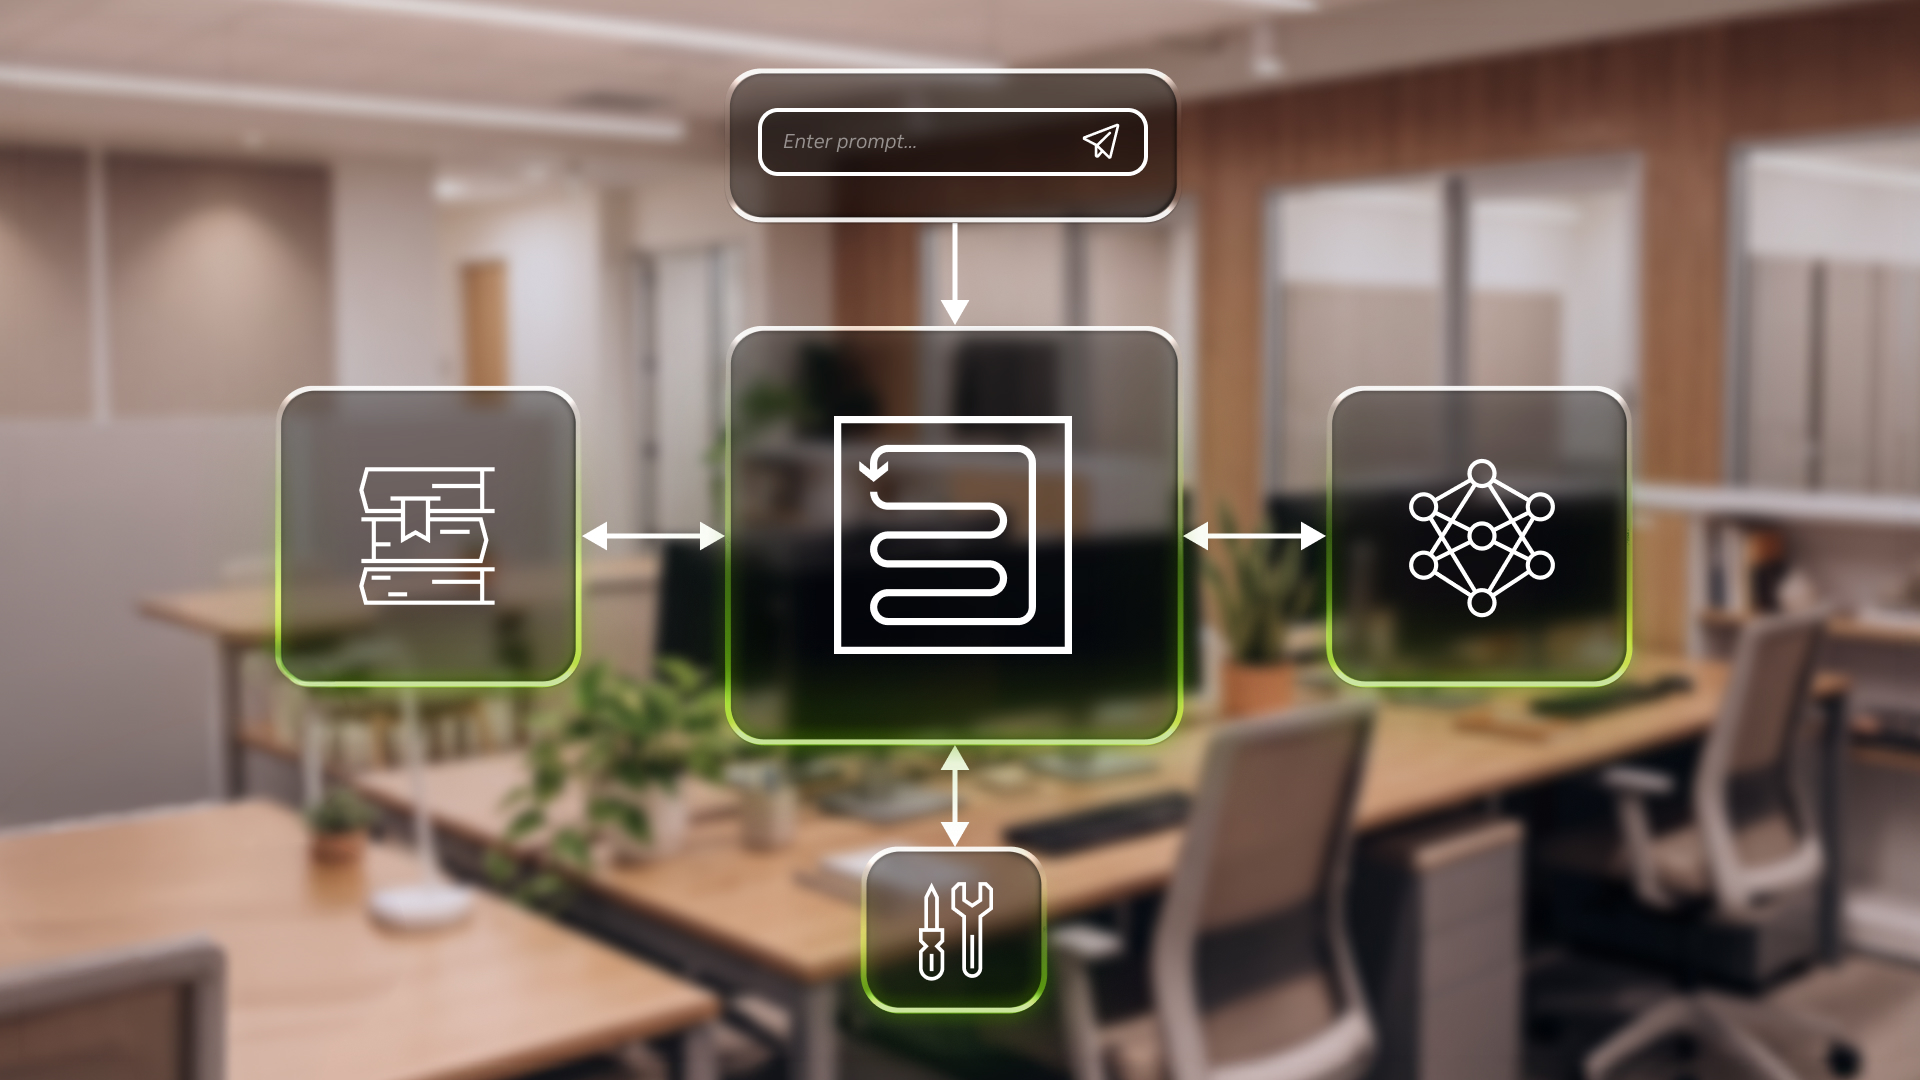
Answer: Yes. Brev.dev’s orchestration layer lets you route requests to different models based on task type (e.g., Nemotron 3 Super for planning, a smaller LLaMA‑based model for summarization). This “model‑as‑service” architecture enables cost‑effective specialization.
Q5: How does the pricing of Brev.dev compare to using raw cloud GPU instances?
Answer: Brev.dev charges a modest platform fee (≈ 5 % of underlying compute spend) plus any cloud provider rates. The platform’s auto‑scaling and utilization insights typically reduce overall spend by 15–25 % compared with manually managed instances, especially when workloads have variable demand.
Closing Thoughts
The debate that unfolded on the Builders Stage was less about ideology and more about operational pragmatism. Startups that treat AI as a strategic asset—balancing immediate speed with long‑term control—will emerge with healthier margins and stronger defensibility. Nvidia’s dual‑pronged strategy—open‑source leadership with Nemotron 3 Super and infrastructure flexibility via Brev.dev—offers a concrete roadmap for that balance.
Whether you’re a solo founder sketching a proof‑of‑concept or a Series B team scaling to millions of users, the key takeaway is clear: don’t view open and closed AI as mutually exclusive choices. Embrace a phased, hybrid approach, leverage the tooling ecosystem Nvidia is cultivating, and keep an eye on the evolving cost‑vs‑control landscape. The next wave of AI‑driven startups will be those that can pivot seamlessly between the two worlds, extracting the best of both to fuel innovation and growth.
Source: Original Article